
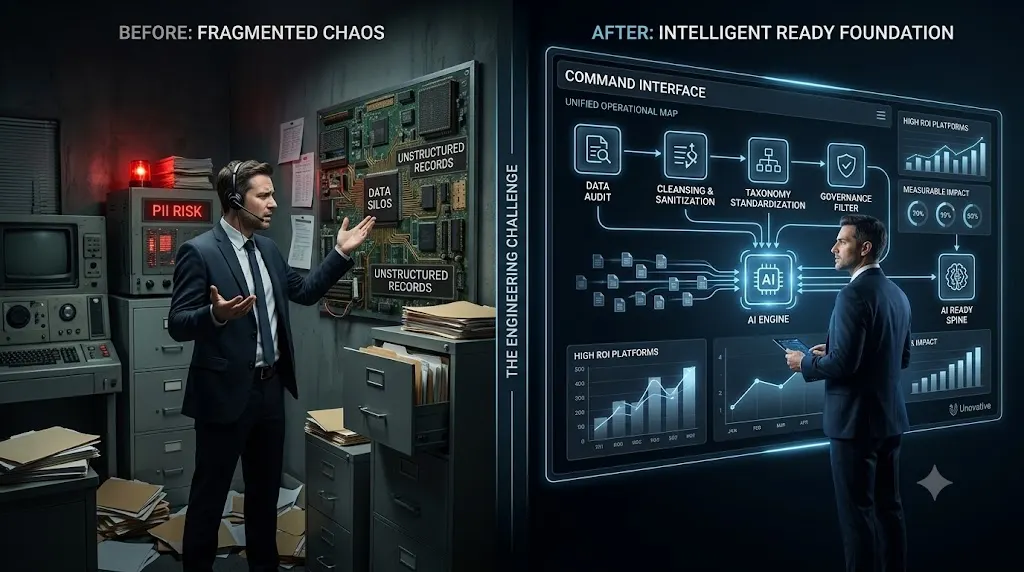
The global enterprise landscape is experiencing a definitive shift in how executive leadership approaches emerging technology. Organizations are no longer debating whether artificial intelligence will reshape their respective sectors. Instead, the mandate from boardrooms across industries from heavy manufacturing and maritime logistics to financial services and modern retails clear: integrate intelligent automation, harness machine learning, and deploy custom AI software to maintain market share.
Yet behind the breathless headlines celebrating generative platforms and algorithmic breakthroughs lies an uncomfortable enterprise reality. Industry data reveals that the vast majority of AI and automation initiatives stall during the pilot stage, fail to scale, or quietly produce inaccurate results that undermine organizational trust.
When an AI initiative fails, executive teams tend to place the blame on the machine learning algorithm, the model framework, or the underlying technology stack. In truth, the algorithms are rarely the source of failure.
Artificial intelligence does not think; it calculates patterns based on the historical and operational information fed into its architecture. If that underlying repository is fragmented across outdated departmental spreadsheets, contaminated with historical entry errors, unstandardized, or trapped behind disparate internal systems, the AI model will inevitably magnify those flaws.
Before committing enterprise capital to intelligent platforms, leadership must recognize an essential principle: AI readiness is fundamentally a data engineering challenge.
As a dedicated digital design, software development, and technology consulting firm helping forward thinking enterprises engineer scalable digital products, we know that successful AI adoption demands disciplined groundwork long before a single model is deployed.
Here is a structured, step by step roadmap for preparing enterprise data to ensure your custom AI software delivers measurable business impact.
- Demolishing Departmental Silos and Mapping Data Ingestion
In most mature enterprises, operational data does not reside in a unified ecosystem. Over years of growth, departments organically deploy their own tools, developing isolated operational islands:
The CRM Dilemma: The sales organization tracks interactions, pipeline status, and client communication inside modern customer relationship tools. Operational Blind Spots: Shop floor operations, logistics managers, or technical superintendents record equipment metrics, dispatch logs, and service reports inside on premise legacy systems or offline logs. Financial Separation: The finance department reconciles invoices, margin calculations, and accounts payable across dedicated accounting platforms that rarely communicate with Realtime delivery channels. Unstructured Records: Crucial corporate knowledge such as technical manuals, contract negotiations, compliance documentation, and inspection logsis trapped within email inboxes, local desktop folders, and physical binders.
If you attempt to layer an artificial intelligence model on top of this fractured landscape, the system encounters an immediate context gap. An AI tool cannot forecast project profitability if it cannot see actual labor costs from operations alongside sales agreements. It cannot predict machinery failure if sensor logs cannot be cross referenced with past supplier spare parts orders.
The Remediation Strategy:
Conduct a Comprehensive Data Discovery Audit: Map out every single location where enterprise information is created, stored, modified, and archived. Identify who manages each repository, what format it exists in, and who has administrative rights.
Build Unified Data Pipelines: Transition away from manual file sharing toward modern API connections, centralized data lakes, or a custom enterprise software backbone. The objective is to establish an accessible, single source of operational truth across all business units.
- Cleansing and Sanitizing Legacy Operational Data
A foundational rule of computer science remains absolute in the machine learning era: garbage in, garbage out. However, in the context of enterprise AI, bad inputs do not just return bad data they introduce systemic risk.
When raw data is fed into an algorithm without rigorous cleansing, the model internalizes duplicate entries, clerical typos, missing fields, and historical outliers as operational truth. For example, if your procurement history contains ten variations of a single vendor’s legal entity name, an intelligent procurement agent will fail to aggregate corporate spend accurately, generating skewed pricing forecasts.
Duplicate entries generated across departments distort predictive statistics. Inconsistent schemas between legacy systems cause model ingestion errors and pipeline crashes. Human clerical errors and missing units lead to hallucinated business outputs, while structurally incomplete datasets hardcode operational bias directly into automated decision making workflows.
The Remediation Strategy:
Automated Data Sanitization: Deploy automated data pipeline scripts to identify, isolate, and remove redundant records, trailing spaces, and formatting corruptions across legacy storage. Establishing Validation Rules at Ingestion: Prevent bad data from entering the database in real time. Implement strict validation criteria in your daily enterprise applications such as mandatory inputs, standardized dropdown selections, and format checking logic to enforce ongoing data consistency. Handling Incomplete Records Systematically: Decide whether legacy records missing crucial parameters should be backfilled through audited manual reviews or cleanly segregated from the training dataset to prevent skewing the model.
- Standardizing Taxonomy and Data Normalization
Even when data is clean, it is often expressed in contradictory dialects across separate business units. Operations might measure equipment performance in metric units, while offshore contracts reference imperial standards. The sales department may label a transaction "Closed Won," while the delivery team tags the exact same event as "Active Onboarding."
To an artificial intelligence algorithm, these stylistic discrepancies represent entirely different parameters. Without standardized taxonomies, the platform cannot connect historical events, leading to fragmented analytics and misinformed operational recommendations.
The Remediation Strategy:
Enterprise Wide Data Dictionaries: Define and document a universal corporate ontology. Every metric, project phase, customer lifecycle stage, and equipment identifier must have an unambiguous, enterprise wide definition. Normalization Pipelines: Build transformation scripts within your data pipeline that normalize timestamps across time zones, standardize currencies to a baseline exchange rate, and unify measurement units prior to analytical ingestion.
- Fortifying Data Governance, Security, and Compliance
Deploying AI software within an enterprise radically expands the organization’s cybersecurity surface area. Connecting large language models (LLMs) or autonomous agentic workflows to internal repositories means that an algorithmic interface now has direct access to corporate intellectual property, sensitive pricing strategies, and protected employee records.
Without robust data governance frameworks, organizations expose themselves to data leakage, regulatory noncompliance, and severe security compromises. Enterprise data must pass through a strict governance filter encompassing access control, data anonymization, and regulatory verification before reaching any automated agent.
The Remediation Strategy:
Enforce Role Based Access Control (RBAC): Not every AI interface should have unrestricted visibility across all corporate records. A customer service AI agent must never be granted access to payroll records or internal executive memos. Strict query level permissions must mirror corporate security hierarchies. Anonymization and Masking of PII: Automatically scrub or encrypt Personally Identifiable Information (PII), proprietary source code, and confidential commercial clauses before datasets are processed by machine learning systems. Immutable Audit Trails: Maintain comprehensive, tamperproof logs of every data query, ingestion cycle, and automated decision made by the AI platform to satisfy external audits and regulatory obligations.
- Structuring Unstructured Data for Modern Architectures
A substantial portion of any enterprise's most valuable intelligence does not sit neatly inside relational database rows and columns. It is buried within unstructured formats: PDF operating procedures, contracts, email threads, maintenance logs, and vendor invoices.
Modern AI architectures, particularly Retrieval Augmented Generation (RAG), specialize in surfacing insights from unstructured documentation. However, an algorithm cannot parse a blurry image of a scanned fax or navigate an unindexed, 500page operational manual effectively without preprocessing.
The Remediation Strategy:
Optical Character Recognition (OCR) Pipelines: Digitize legacy paperwork using high accuracy OCR tools, converting static image based PDFs into machine readable digital text. Semantic Chunking and Metadata Tagging: Break dense enterprise documentation into logical, contextual segments. Enrich every chunk with robust metadata tags including document date, author, department, revision version, and access level to enable accurate vector retrieval.
- Aligning Preparation with Concrete Business Objectives
Data preparation is an extensive engineering undertaking; it should never be executed as an abstract academic exercise. Attempting to clean decades of historical enterprise data without a defined business use case leads to scope creep, exhausted budgets, and project fatigue.
Successful enterprise transformations always adopt a problem first approach:
Identify the Core Commercial Problem: Determine the precise operational pain point you need the AI system to solve. Is it predicting high wear machinery breakdowns before they delay shipments? Is it accelerating cross departmental procurement approvals? Is it automating repetitive customer onboarding inquiries?
Curate the Specific Dataset: Once the target objective is locked in, isolate the exact data streams required to power that specific outcome. Cleaning 10,000 highly relevant, perfectly curated operational records delivers infinitely more value than dumping millions of messy, irrelevant files into an algorithm.
Validate with an MVP: Deploy a focused Minimum Viable Product (MVP) on your prepared dataset, observe how the system performs under real operational conditions, and refine your data hygiene protocols based on practical output metrics.